Best AI Literature Review Tools: Why Semantic Search Misses Papers and How to Build a Reproducible Protocol
Discover why the best AI literature review tools miss key studies. Learn how to build a reproducible, hybrid search protocol for Master's and PhD research.
The Hidden Recall Crisis in Automated Literature Discovery
Graduate researchers navigating dissertation milestones increasingly encounter promises that machine learning can automate their initial scoping phase. However, empirical assessments reveal a stark disconnect between vendor marketing and systematic review standards. While the best AI literature review tools accelerate exploratory scanning and thematic clustering, relying exclusively on probabilistic algorithms introduces substantial methodological risk into your literature synthesis.
Independent evaluations demonstrate that AI-assisted search workflows frequently exhibit high precision alongside alarmingly low recall. In one controlled benchmarking study, an AI-assisted search achieved a precision rate of 76.2% but a recall rate of only 38.1%—meaning the system missed over six out of ten relevant studies. When evaluating candidate studies, precision measures the proportion of retrieved documents that are truly relevant, whereas recall measures the proportion of all existing relevant documents that the search successfully captured. In systematic scholarship, high precision cannot compensate for low recall.
A parallel evaluation of popular research assistants revealed that semantic platforms retrieved approximately 40% of the foundational studies incorporated in gold-standard human reviews, whereas traditional systematic searches indexed approximately 95%. When writing an academic dissertation, missing foundational papers undermines theoretical coherence and leaves you vulnerable during committee reviews and viva examinations. A literature review that omits seminal works or conflicting empirical evidence distorts the intellectual landscape of your field.
To protect the scholarly rigor of your work, you must understand the mechanical failure points of semantic search. Platforms like Thesionyx approach literature synthesis not as an unsupervised autocomplete task, but as a bounded, auditable workflow. By combining deterministic multi-database indexing with controlled semantic discovery, postgraduate researchers can capture comprehensive literature without sacrificing reproducibility.
Why Semantic Algorithms Miss Core Empirical Research
The primary vulnerability of standalone AI research tools is their opaque retrieval mechanics. Unlike Boolean systems that execute strict logical sets, semantic search engines rely on vector embeddings. These mathematical representations calculate linguistic proximity, returning papers whose language mirrors your prompt. While useful for exploratory ideation, this mechanism fails across several predictable vectors:
Vocabulary mismatch and domain shifts represent a primary failure mode. Semantic models map words into vector spaces based on co-occurrence probabilities. Consequently, they struggle when fields undergo terminological evolution or rely on discipline-specific framing. A prompt examining pedagogical friction may completely bypass foundational papers framed entirely around instructional dissonance or cognitive load theory, despite identical conceptual cores.
Opaque and incomplete indexing compounds this issue. Proprietary academic assistants rarely disclose their complete index coverage or licensing constraints. Traditional curated databases like PubMed, Scopus, and Web of Science index millions of peer-reviewed articles under disciplined metadata controls. Conversely, consumer AI discovery tools frequently harvest open-access repositories or uncurated preprint aggregators, omitting closed-access journals that host seminal foundational studies.
Metadata gaps further erode discovery recall. When repositories fail to capture digital object identifiers (DOIs), structured author keywords, or publication classifications, vector calculations fail to index those records accurately.
Finally, algorithmic popularity bias skews automated discovery. Vector retrieval systems frequently optimize ranking functions using citation counts and network prominence. In one comparative evaluation, AI-selected papers averaged 202 citations, compared to just 64.4 citations for papers selected by human researchers. This bias suppresses cutting-edge preprints, negative results, and localized empirical studies. When conducting research, these invisible blind spots leave serious gaps in your background reading. Discovering that your theoretical framework overlooked three critical empirical papers after your committee review is a preventable setback.
Comparing Leading AI Research Tools and Platforms
To select the right workflow, researchers must evaluate tools across auditability, corpus depth, and recall performance. Consumer tools are optimized for user convenience, whereas academic thesis preparation requires reproducible documentation. Understanding the structural differences among discovery architectures prevents catastrophic coverage errors during comprehensive literature reviews.
| Tool / Platform | Primary Strength | Corpus Visibility | Reproducibility Rating | Best Suited For |
|---|---|---|---|---|
| Thesionyx | Source-grounded thesis drafting & defense | High (User-verified) | High (Audit-trailed) | Master's & PhD theses |
| Elicit | Rapid data extraction & matrix building | Moderate (Open-access bias) | Moderate (Semantic drift) | Preliminary scoping |
| Scopus AI | High-impact overview of indexed corpus | High (Scopus database) | Moderate (Query variance) | Institutional discovery |
| Semantic Scholar | Exploratory citation graphing | Moderate (Open index) | Low (Dynamic ranking) | Seed paper discovery |
| Rayyan | Systematic review screening workflows | High (Uploaded RIS/BibTeX) | High (Deterministic logic) | PRISMA team screening |
Most third-party tools prioritize rapid summarization over defensible attribution. For instance, tools like Elicit claim time savings of up to 80% during review extraction. However, independent research shows query instability: identical queries run across separate sessions in proprietary AI interfaces produce divergent results in roughly half of repeated attempts.
For doctoral candidates, this non-deterministic output violates basic academic reproducibility requirements. If an external examiner attempts to replicate your search string within an unconstrained semantic interface, differing weights or live corpus updates will yield an altered paper pool. Thesionyx solves this instability by locking source files inside The Vault, ensuring that every citation, extraction, and synthesis decision is anchored to verifiable DOIs and static full-text records. This eliminates procedural drift while retaining modern analytical capabilities.
Building an Auditable and Reproducible Hybrid Protocol
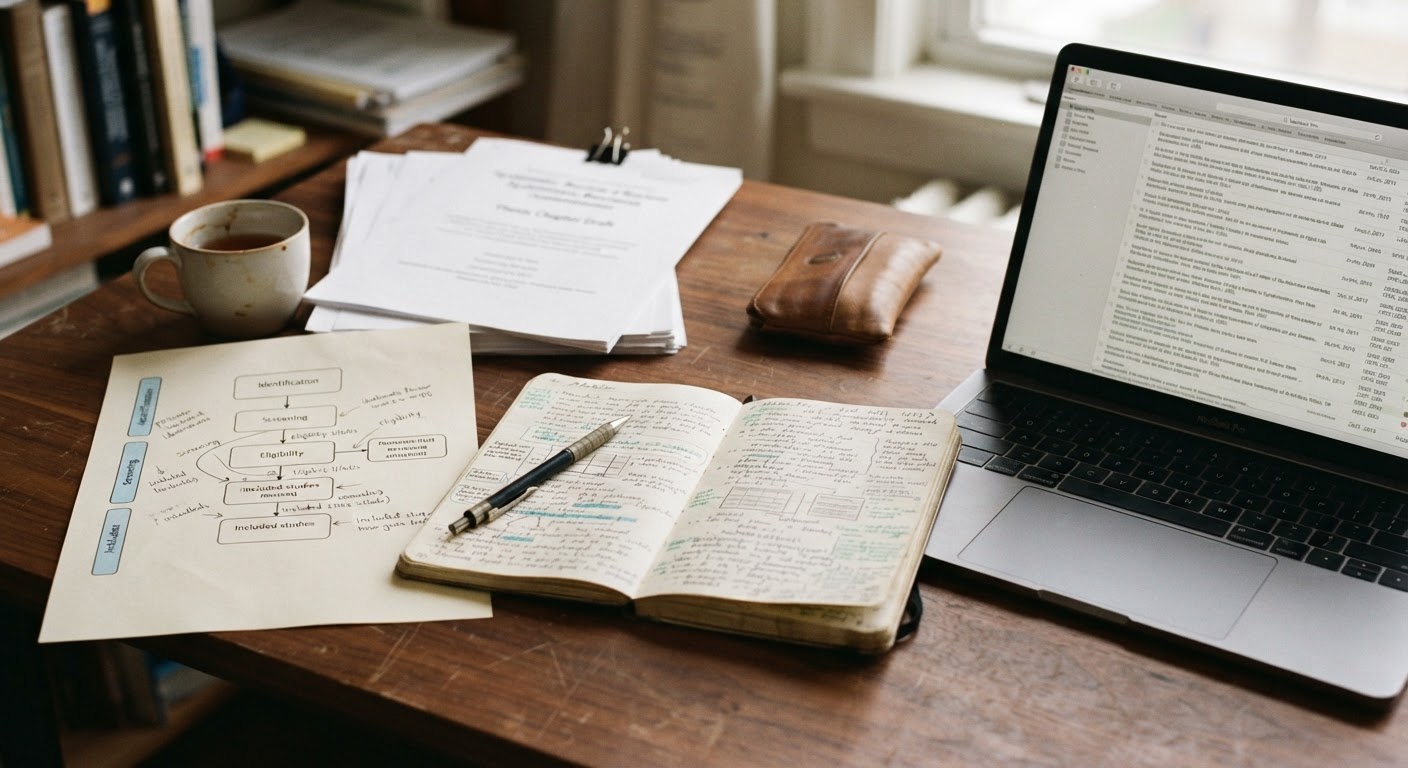
A publication-grade literature review requires an auditable trail that conforms to recognized methodological guidelines, such as PRISMA (Preferred Reporting Items for Systematic Reviews and Meta-Analyses). Rather than abandoning artificial intelligence, researchers should integrate it within a defensible, multi-stage protocol that leverages machine learning without ceding scientific governance to black-box systems.
First, construct deterministic Boolean baselines. Develop a structured search string incorporating standardized field tags, exact Boolean operators (AND, OR, NOT), and truncation wildcards. Execute this string across at least two major institutional databases, such as PubMed, IEEE Xplore, PsycINFO, or Scopus. Boolean operations preserve clear set-theoretic boundaries that remain completely reproducible over time, establishing an uncompromised foundational pool.
Second, export and preserve raw search logs immediately. Download raw bibliographic metadata (in RIS or BibTeX formats) directly from the native interfaces. Maintain a version-controlled master log recording the explicit string syntax, platform vendor, applied database filters, and precise UTC timestamps. This step guarantees that your baseline corpus is frozen against external algorithmic volatility.
Third, deploy bounded AI for terminology expansion rather than direct paper selection. Use semantic assistants strictly to surface missing MeSH terms, related synonyms, and conceptual adjacencies. If an AI tool suggests relevant candidate papers, extract their controlled vocabulary terms and fold them back into your formal Boolean query for transparent re-execution.
Fourth, execute systematic forward and backward citation chasing. Seminal research frequently sits inside citation networks rather than top-ranked search results. Examine the reference lists of your top five most relevant empirical papers, and track subsequent publications that cited them. By maintaining strict boundaries between deterministic database retrieval and heuristic AI exploration, you protect your research against unpredictable algorithmic shifts.
Deduplication, Title-Abstract Screening, and Quality Appraisal
Once you compile your candidate records, deduplication and screening become the most resource-intensive steps. Machine learning delivers genuine value here when applied as a screening prioritization filter rather than an automated inclusion judge. Uncritical reliance on autonomous screening introduces significant risk, as models often misunderstand subtle methodological exclusions.
Begin by deduplicating your exported libraries using programmatic tools such as EndNote, Zotero, or dedicated deduplication packages in R (such as synthesisr). Remove exact duplicates across databases before evaluating partial matches with discrepant metadata. Next, import your clean dataset into a dedicated screening environment like Rayyan or Thesionyx.
When using machine learning to prioritize title and abstract screening, configure the algorithm to rank papers by relevance based on your explicit inclusion criteria (e.g., empirical design, publication window, population sample). Human reviewers must still examine excluded studies near the decision boundary.
### Literature Review Search Audit Log

- **Review Question:** What is the impact of task-based language teaching on adult second language acquisition?

- **Databases Queried:** ERIC, Scopus, Web of Science

- **Search Date:** 2026-03-15

- **Boolean Query:** ("task-based language teaching" OR "TBLT") AND ("adult learner*" OR "higher education") AND ("second language acquisition" OR "L2")

- **Filters Applied:** Peer-reviewed, English language, 2015-2026

- **Raw Yield:** ERIC (214), Scopus (342), Web of Science (188) | Total: 744

- **Deduplicated Yield:** 512 records

- **AI-Assisted Scoping Additions:** 14 unique papers identified via semantic vector matching

- **Final Screened Pool:** 526 records
Maintaining a transparent screening log protects you against supervisory pushback and demonstrates methodological rigor in your dissertation methods chapter. The log must account for every eliminated record through defensible inclusion and exclusion criteria.
Source Grounding and Eliminating Hallucinations in Thesis Writing
Synthesizing evidence across dozens of studies introduces significant cognitive load, which is where many researchers inadvertently introduce attribution errors. Consumer large language models generate fluid prose that sounds authoritative but frequently severs the connection between an empirical claim and its source data. In an academic thesis, citing a statistical conclusion or theoretical framework that cannot be mapped to a specific page or dataset is disqualifying.
Source grounding requires that every assertion generated during your writing workflow directly references a verified full-text document. If you extract sample sizes, effect sizes, or methodological frameworks, use software that displays the source PDF alongside the extracted summary. This deterministic anchoring guarantees that conceptual synthesis remains tethered to verified empirical findings.
Furthermore, you must account for institutional policies. Leading universities across the United States, the UK, and Australia mandate strict disclosures regarding AI assistance. Academic integrity boards do not permit submitting AI-generated summaries as original scholarship.
Instead, treat automated synthesis as an indexing aid: let it extract structured comparison tables, but write the critical evaluation yourself. Verify that every cited paper exists, confirm that the digital object identifier is valid, and read the original text before incorporating any finding into your literature review. Relying on verified full-text repositories mitigates phantom citations and protects your scholarly credibility.
Defending Your Literature Synthesis in Viva Examinations
A comprehensive literature review is not merely an academic exercise; it forms the foundation of your oral defense. In university viva examinations across the United States, committee members routinely probe the perimeter of your bibliography. They will test why specific historical papers were excluded, ask you to justify your methodology against competing paradigms, and examine how your work addresses contradictory findings.
If your literature review relies on consumer AI tools that favor popular, highly cited articles, you will struggle when examiners ask about niche regional studies or methodologically challenging counter-evidence. A resilient literature review demonstrates that you understand the historical evolution of your discipline.
### Committee Defense Readiness Checklist

1. Provenance Trail: Can you produce the exact database queries and date stamps for your systematic search?

2. Negative Findings: Did your search strategy retrieve studies with null or conflicting outcomes?

3. Foundational Lineage: Can you trace your primary theoretical model back to its original formulation?

4. Methodological Variance: Have you accounted for variations in sample sizes, instruments, and geographic contexts?

5. Direct Verification: Have you read and verified every cited source in your final bibliography?
Preparing for defense questions requires interrogating your own claims under adversarial conditions. Practicing with targeted mock examinations ensures that you can defend your inclusion choices and articulate your contributions with confidence. Examiners respect methodological transparency; being able to point to an explicit, audit-trailed hybrid protocol transforms a potential critique of your bibliography into evidence of rigorous scientific design.
About Thesionyx
Thesionyx is an AI-powered operating system designed to assist researchers and higher-education students in drafting source-grounded theses and preparing for viva defenses. Serving scholars across the United States, the United Kingdom, Canada, Australia, and worldwide, Thesionyx bridges the gap between modern artificial intelligence and rigorous academic integrity.
Rather than generating ungrounded text, Thesionyx provides specialized modules including The Vault for verifiable source management, a Literature Review Generator, a Thesis Chapter Drafting Tool, an Academic Critique Engine, a Live Viva/Defense Simulator, and a Citation Validator. Every tool within the suite operates under a strict verification paradigm, ensuring that postgraduate writers maintain total control over their scholarship, eliminate citation errors, and defend their dissertations successfully.
By confining AI analysis strictly to verified, uploaded academic literature, Thesionyx ensures full transparency and auditability. Researchers can interrogate their corpora, generate comparative extraction matrices, and identify conceptual divergences across studies without risking ungrounded assertions. Explore our platform and register to secure your place for the upcoming academic cohort at Thesionyx.com.
Frequently asked questions
Why do AI literature review tools miss crucial empirical papers?
AI discovery tools rely on high-dimensional vector embeddings that calculate linguistic proximity rather than boolean logic. In empirical benchmarking, these models demonstrate high precision but alarmingly low recall—frequently missing over 60% of eligible empirical studies. They struggle with terminological drift, historical vocabulary changes, and non-standardized keywords. Furthermore, opaque underlying corpora and algorithmic popularity biases favor heavily cited, established works while suppressing niche, regional, or newly published studies.
Can I rely entirely on an AI tool for a systematic literature review?
No. Established review frameworks like PRISMA mandate complete procedural transparency, including reproducible search strings, explicit institutional database coverage, unalterable search logs, and deterministic outputs. Proprietary AI tools use non-deterministic probabilistic ranking that changes over time, producing divergent results for identical queries. While AI tools are valuable for preliminary scoping, synonym generation, or screening triage, they cannot replace deterministic multi-database Boolean execution.
What is algorithmic popularity bias in academic search engines?
Algorithmic popularity bias occurs when semantic vector rankers incorporate citation counts, journal impact metrics, or digital centrality into their relevance scoring. Comparative analyses show AI-curated corpora average over 200 citations per paper, compared to approximately 64 citations in human-screened systematic reviews. This skews results toward legacy consensus, suppressing critical negative results, small-cohort empirical studies, and recent preprints essential for balanced synthesis.
Is using AI for a PhD literature review permitted by institutional guidelines?
Most global research institutions permit AI tools for assistive tasks—such as exploratory search, coding assistance, or language polishing—provided usage is transparently disclosed. However, policies strictly prohibit submitting ungrounded synthetic text as original scholarship or using automated tools without manual verification. Researchers must produce exact audit logs, verify all bibliographic metadata against primary PDFs, and independently synthesize their theoretical arguments.
How does Thesionyx prevent citation hallucination in academic writing?
Unlike unconstrained consumer LLMs that predict probable token strings, Thesionyx enforces closed-loop retrieval-augmented verification. Through The Vault, text synthesis and extraction are hard-bounded exclusively to user-uploaded, verified PDF source documents. The platform's Citation Validator verifies every extracted claim against page-level source text and valid Digital Object Identifiers (DOIs), eliminating fabricated studies and phantom citations.
What is the ideal workflow for combining traditional databases with AI tools?
Begin with deterministic Boolean queries across at least two traditional indexing databases (e.g., Scopus, Web of Science). Export raw RIS or BibTeX files with full timestamps. Next, run exploratory semantic queries in bounded AI tools to extract overlooked synonyms and MeSH terms, feeding them back into your Boolean logic. Finally, conduct bidirectional citation chasing, perform deduplication, and verify all full-text documents in a grounded environment.
About Thesionyx
An AI-powered operating system designed to assist researchers and higher-education students in drafting source-grounded theses and preparing for viva defenses.
Expert services sold to organisations — legal, accounting, agency, consultancy, engineering.
request a quote or get in touch with ThesionyxNext step
Continue with Thesionyx
An AI-powered operating system designed to assist researchers and higher-education students in drafting source-grounded theses and preparing for viva defenses.
Visit ThesionyxWritten with information published by Thesionyx.